Analytics & BI
Trusted marts and metrics definitions so leadership stops arguing about numbers in meetings.
NASBIX TECHNOLOGIES
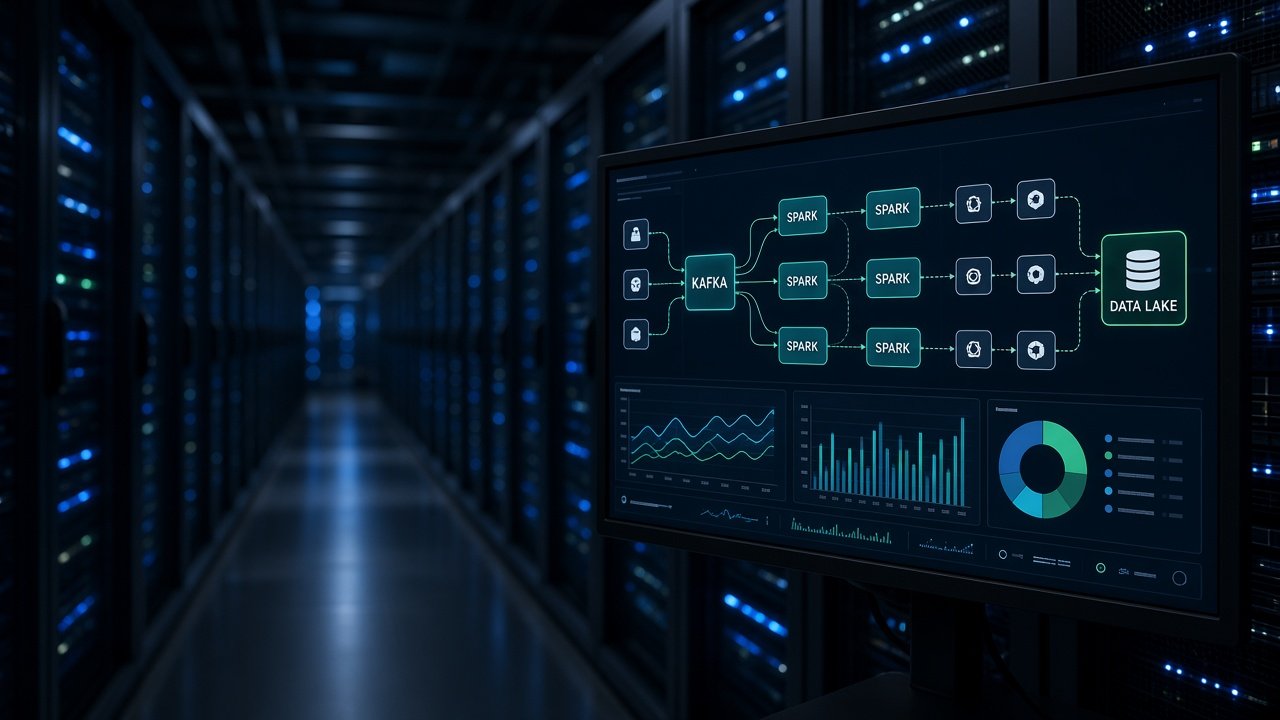
Ingestion, lakehouse architecture, Spark and dbt transforms, streaming and batch jobs—reliable data platforms with quality, lineage, and cost controls from our Karachi delivery center.
Platforms fail when ingestion is fragile, nobody owns schema changes, and finance opens a cloud bill nobody can explain. NASBIX builds data foundations: sources connected, bronze/silver/gold layers documented, transforms tested, and SLAs analytics and ML teams can rely on.
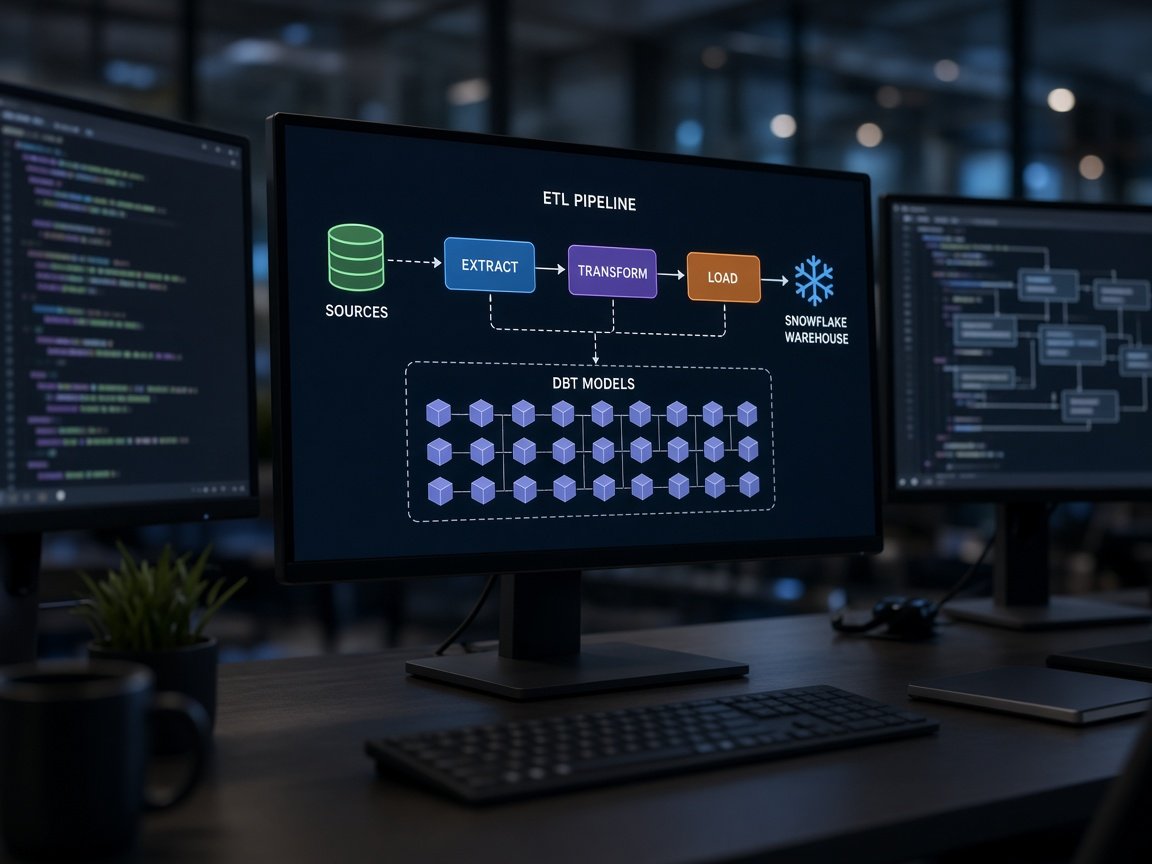
We deliver on AWS, GCP, or Azure—from Kafka and Spark streaming to dbt models on Snowflake, BigQuery, or Redshift. Pair with BI for semantic layers and dashboards, and with AI when RAG and features need fresh, governed corpora.
Greenfield platforms, migrations, and pipeline rescue when jobs fail silently every night.
Trusted marts and metrics definitions so leadership stops arguing about numbers in meetings.
Feature stores, training datasets, and event streams with freshness SLAs models depend on.
Clickstreams, IoT telemetry, and transaction logs at scale—see logistics and IoT patterns.
Production pipelines with observability—not one-off ETL scripts on a forgotten VM.
APIs, databases, files, CDC, and event streams—batch and real time with retry and dead-letter handling.
S3/GCS/ADLS layers, Iceberg/Delta patterns, and warehouse sync with clear retention rules.
Spark, dbt, SQL, and Python jobs—modular, tested, and scheduled with Airflow, Dagster, or cloud native.
Kafka, Kinesis, or Pub/Sub consumers with windowing, joins, and delivery guarantees where required.
Schema registry, data quality checks, lineage metadata, and access policies for sensitive fields.
Monitoring, alerting, runbooks, and FinOps reviews so spend scales with value—not surprise.
We document ownership, on-call expectations, and upgrade paths—so the platform still runs when the first contractor leaves.
Start with highest-value sources and marts—expand coverage without big-bang cutovers.
Architecture and pipeline review with prioritized roadmap and cost/quality findings.
Fixed-scope ingestion and transformation for one domain or product line.
Phased move from legacy stack to cloud lakehouse with parallel run and cutover plan.
Embedded engineers owning pipeline backlog, on-call rotation, and platform upgrades.
ML, BI, and innovation programs built on trustworthy data.